Automated Essay Scoring
Score a handwritten Portuguese essay against the five ENEM competences, from a photograph of the page.
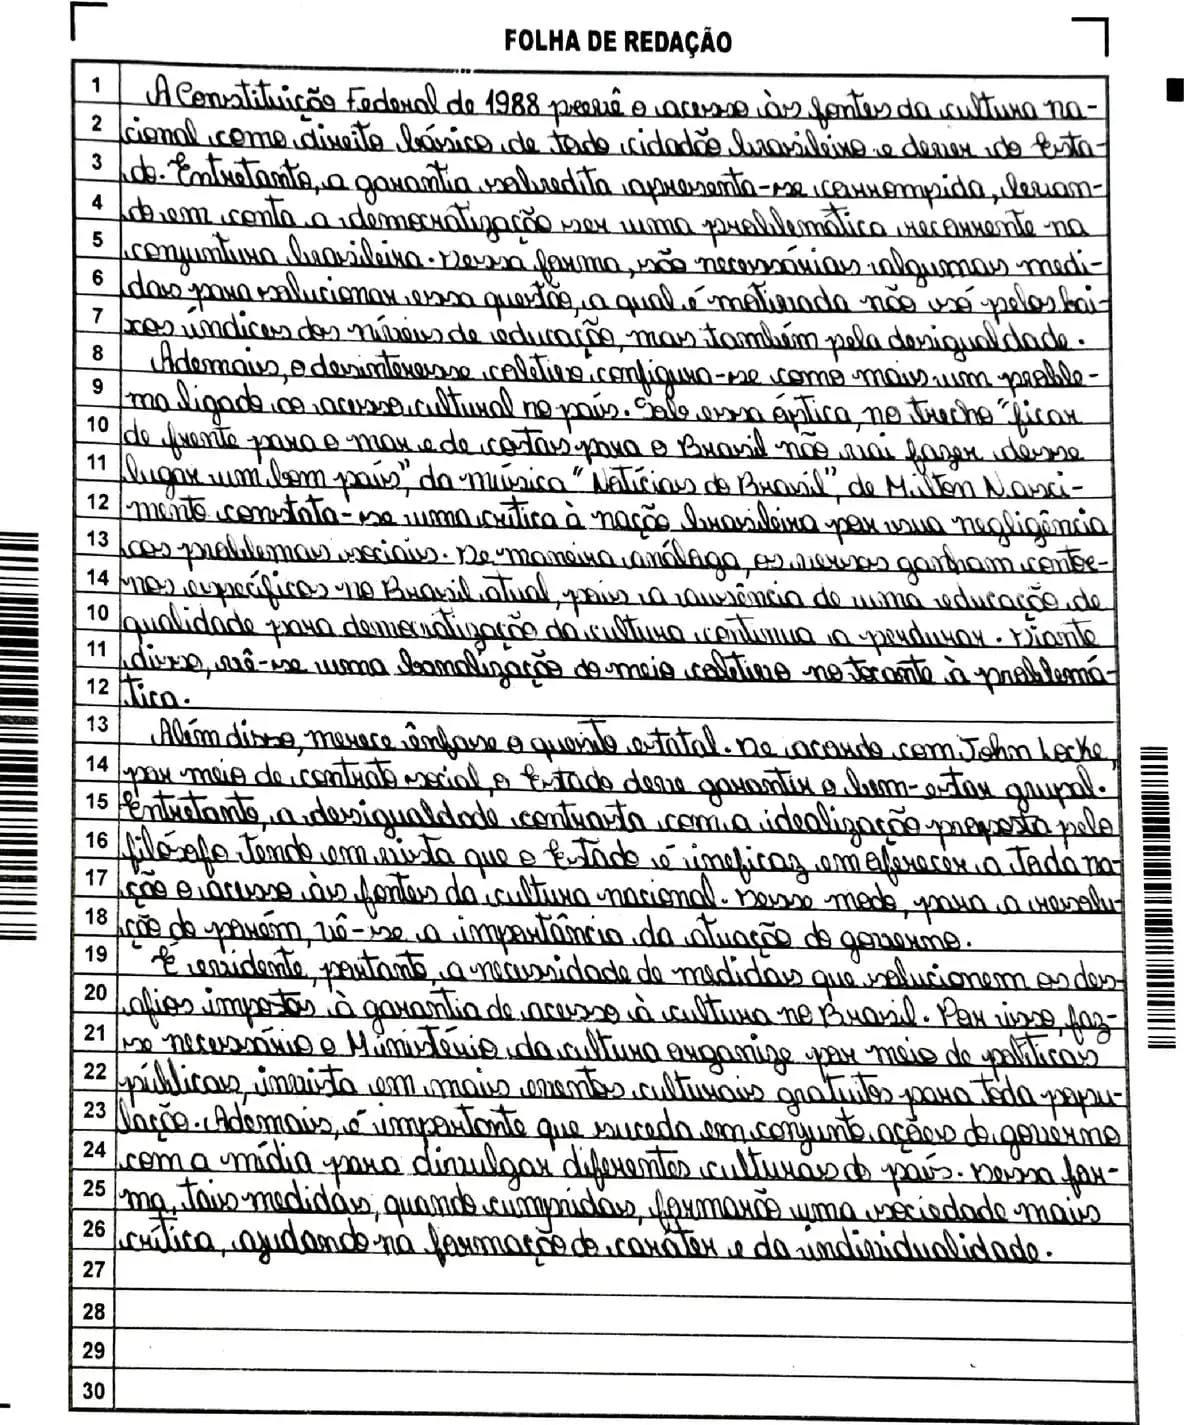
essay-1-18Competences 1 to 5: 160, 200, 160, 160, 200The data for this track is a preview sample of the full AIED-Unplugged collection, which is released at a later date. The prediction format below is the basis for the one the full release will use; the release may refine it and carry data this preview does not, as how the preview was annotated sets out.
The dataset splits this track into 74 train, 20 validation and 24 test items. Train and validation carry their targets. Test carries inputs only and decides the ranking.
The test targets are published once the competition closes, and the dataset pages linked here are updated in place. That completes the preview sample. The full collection arrives separately.
Inputs
One student's redação, as a photograph of the page, together with the prompt it answers and the three textos motivadores printed with it.
Pages are cropped to the written answer, to anonymize the students. The photographs are taken in schools rather than scanned, so they carry skew, shadows, folds, and uneven white balance. No transcription is supplied.
Prediction
Five integers per essay, one for each ENEM competência. Each runs from 0 to 200 in steps of 40, which is how human raters score them, so 0, 40, 80, 120, 160, and 200 are the only values a competence can take. A whole number between two of them is refused before upload, because the grader refuses the whole file for it.
Predictions are graded per competence.
Scoring
The ranking metric is quadratic weighted kappa, averaged over the five competences. QWK measures distance from the human scores relative to the distance raters disagree by, and penalises a two-band miss more heavily than a one-band miss. It is computed over all six possible scores rather than the scores present in the test split, so the value does not shift with the split.
Exact-match rate and RMSE are reported alongside it, along with each competence's own kappa and RMSE.
Prediction format
Files are checked against this declaration before they are submitted.
| Column | Type | Notes |
|---|---|---|
| essay_id | string | Identifier. Must be unique. As the dataset ships it: essay-1-3 |
| competence_1 | integer | |
| competence_2 | integer | |
| competence_3 | integer | |
| competence_4 | integer | |
| competence_5 | integer |
A few rows showing the shape of the file. Its identifiers are placeholders, not the dataset’s.
Permitted scores
Every competence is scored on the same six-point grid. A whole number between them, such as 137, is not a score any rater can award and is refused before upload.
- 0
- 40
- 80
- 120
- 160
- 200
Checked in competence_1, competence_2, competence_3, competence_4, competence_5.
Baselines
Produced by the organizing team and submitted like any other entry. They are marked on the board.
Majority scorebaseline-majority
Predicts the most frequent score for every competence. The floor any model must clear.
Vision model + rubricbaseline-vlm-rubric
Shows a vision-language model the page, the prompt, and the official competence descriptors, with no fine-tuning.